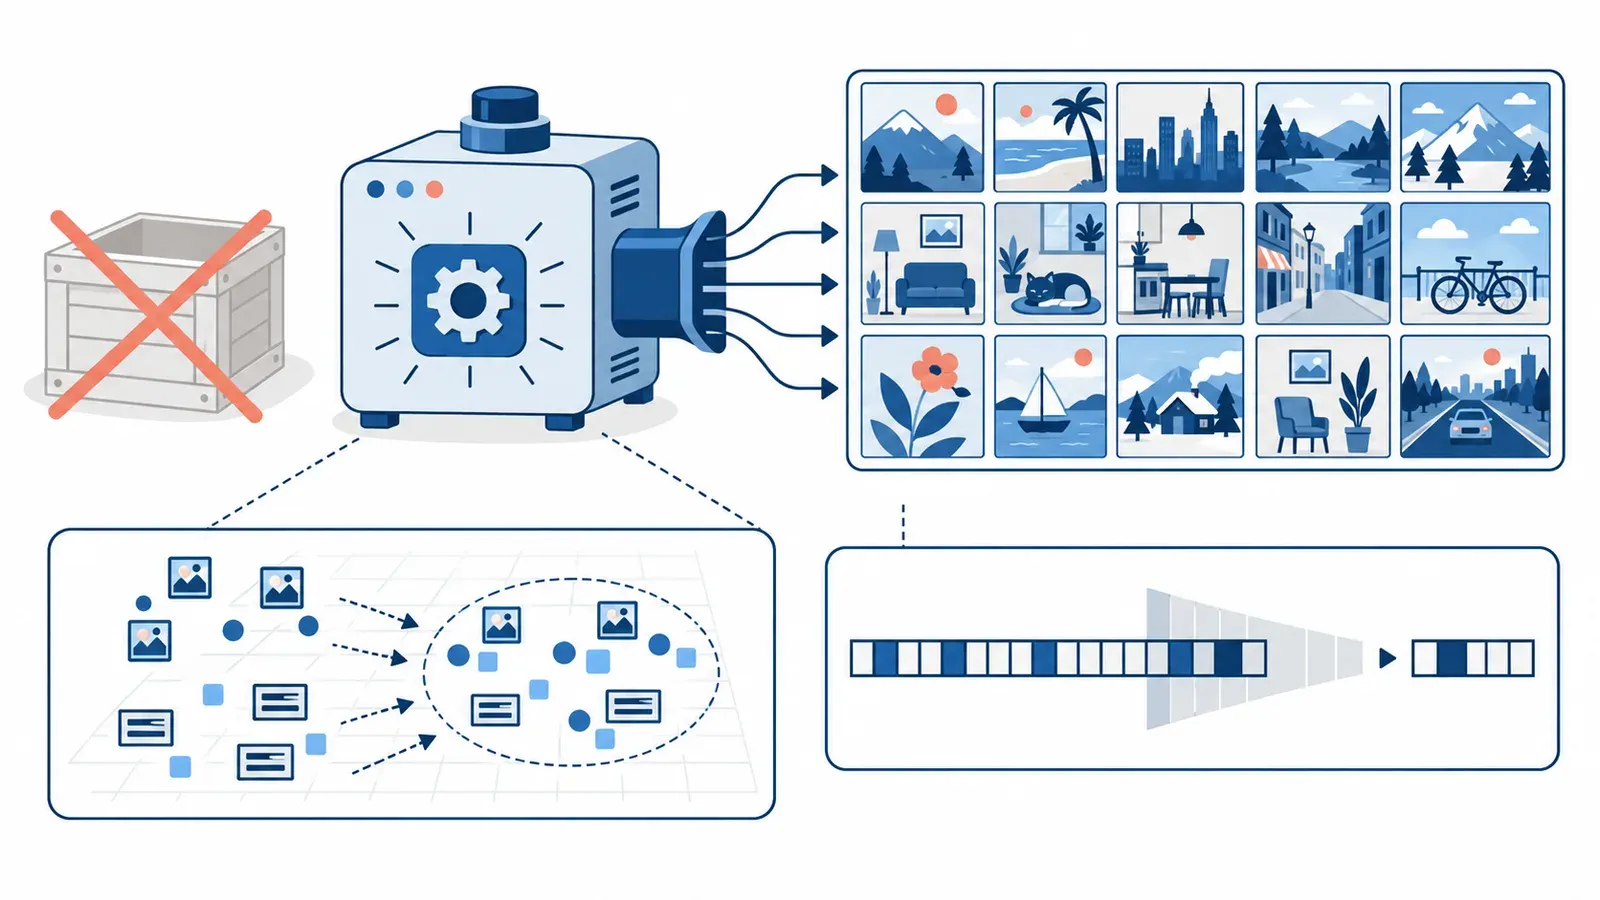
Addresses data-free quantization of CLIP vision-language models by tackling the core challenge of insufficient semantic diversity in synthesized calibration samples. D4C combines prompt-guided semantic alignment, structural contrastive generation for compositional diversity, and perturbation-aware enhancement — enabling effective W4A4 CLIP compression without original training data.