概要
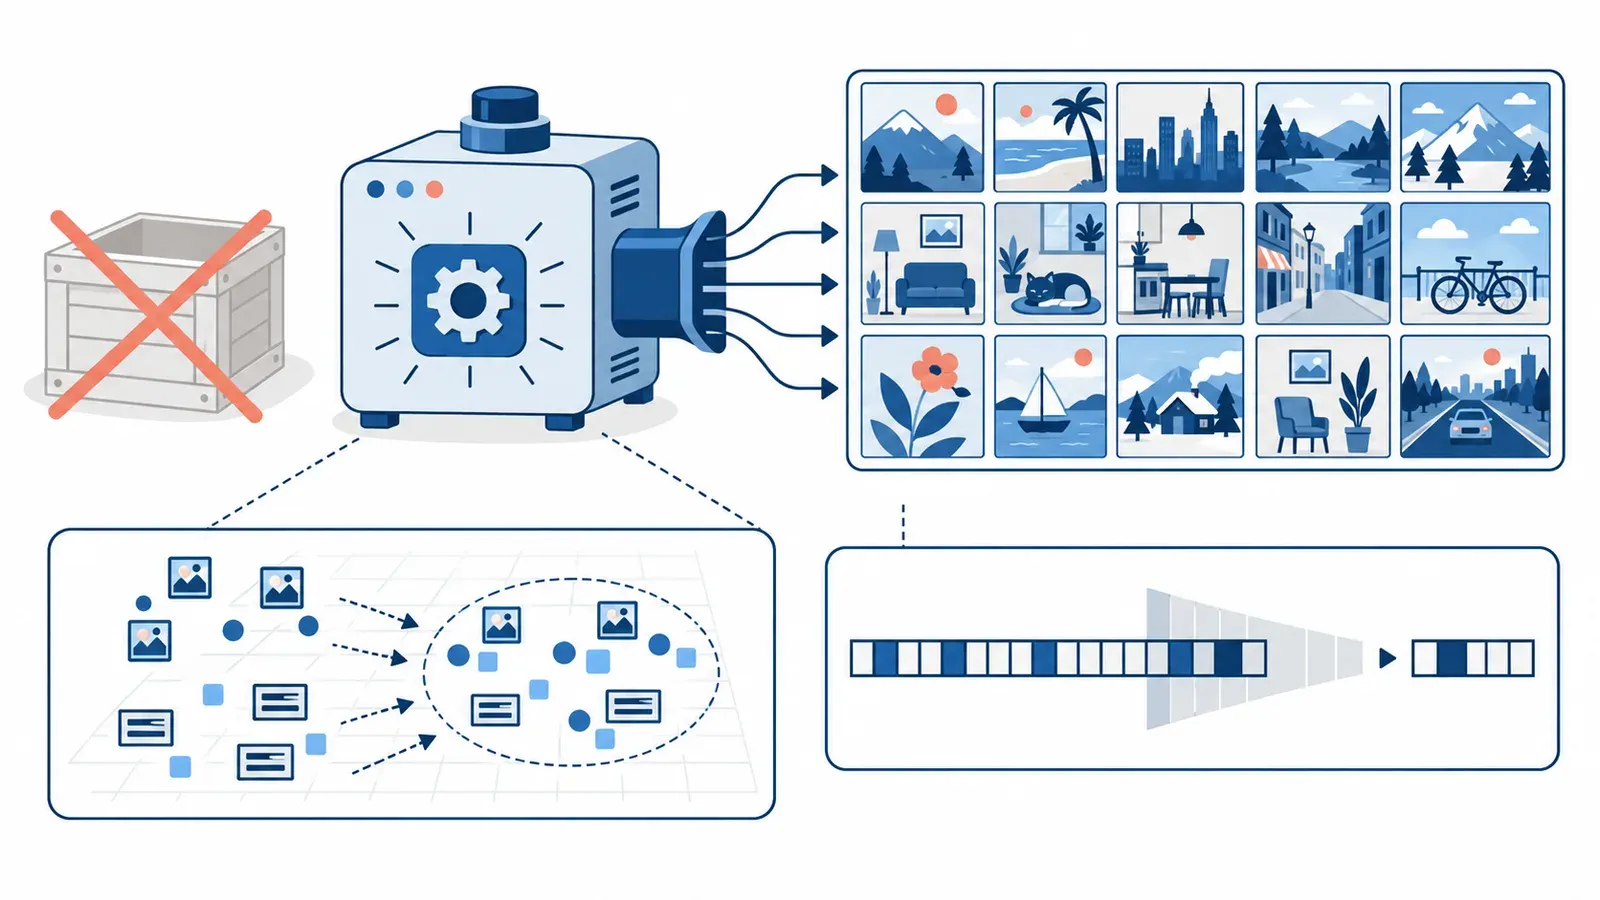
元データを使わずにCLIP(視覚・言語基盤モデル)を量子化するD4Cフレームワーク。合成サンプルの意味多様性不足という課題に対し、プロンプト誘導型セマンティックアライメント・構造的コントラスト生成・摂動ロバスト化の3要素で解決する。W4A4でのCLIP圧縮をはじめてデータなしで実現した。
Addresses data-free quantization of CLIP vision-language models by tackling the core challenge of insufficient semantic diversity in synthesized calibration samples. D4C combines prompt-guided semantic alignment, structural contrastive generation for compositional diversity, and perturbation-aware enhancement — enabling effective W4A4 CLIP compression without original training data.