概要
物体検出を固定パイプラインではなく動的な意思決定として捉えるエージェント型フレームワーク。マルチモーダル大規模言語モデル(MLLM)が中心エージェントとなり、画像復元モジュールと専門検出器のツールボックスから、シーンに応じた処理手順をその場で組み立てる。少量の注釈データから意思決定の経験を蓄積して推論時に活用する DetAS-X により、6つのベンチマークで既存のMLLMベース検出器を平均F1で28.36%、暗所データセットDarkFaceでは最大37.01%上回った。
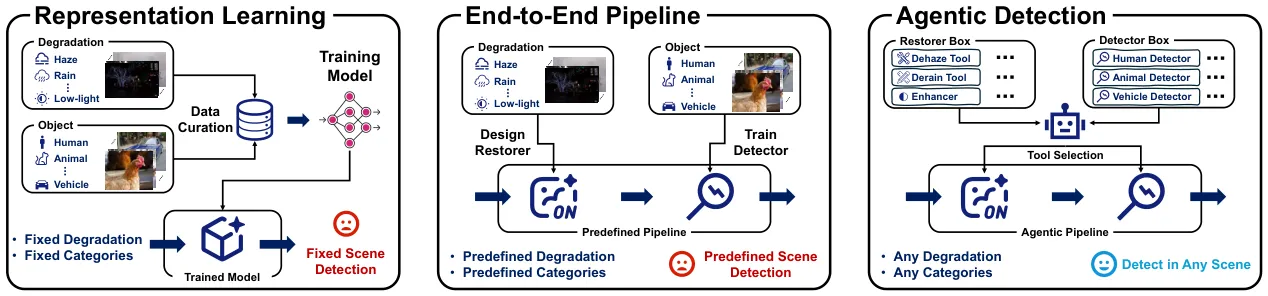
An agentic detection framework that treats object detection as a dynamic decision process rather than a fixed pipeline. A multimodal large language model acts as the central agent, composing a detection workflow per scene by choosing from a toolbox of restoration modules and specialized detectors.
Two components drive it: Self-Adaptive Image Restoration, which decides whether and how to enhance an image before detection, and Multi-Expertise Detection, which reconciles the predictions of several domain-specialized detectors through instance-level reasoning. DetAS-X extends this with Self-Evolving Experience Harvesting, accumulating node-level decision experience from a small annotated set so the system reasons from past decisions at inference time.
Across six challenging benchmarks DetAS-X outperforms existing MLLM-based detectors by 28.36% F1 on average, reaching a 37.01% gain on DarkFace.